

Updated Sep-2026 Test Engine or PDF for the VMware 3V0-25.25 test to help you quickly prepare for the VMware exam!
Full 3V0-25.25 Practice Test and 64 unique questions with explanations waiting just for you, get it now!
NEW QUESTION # 37
Which two statements describe the recommended strategy for configuring and synchronizing security policies across Federated NSX sites? (Choose two.)
- A. Consistency is achieved by ensuring all security groups have the exact same name on every Federated site's Local Manager (LM).
- B. Security policies, such as Distributed Firewall rules and security groups, must be defined as global policies on the Global Manager (GM).
- C. Local Managers (LMs) can define local policies, but any global policies defined on the GM always take precedence over the local ones.
- D. Security policies should be defined locally on each LM and only synchronized manually by an administrator to prevent accidental conflicts.
- E. The Global Manager only synchronizes networking (L2/L3) configurations. Security rules must be configured separately on each site.
Answer: B,C
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
NSX Federationis the cornerstone of multi-siteVMware Cloud Foundation (VCF)security, enabling administrators to maintain a consistent security posture across geographically dispersed data centers. The management of security in a Federated environment relies on a hierarchical relationship between theGlobal Manager (GM)andLocal Managers (LMs).
According to VMware documentation, the recommended strategy is to defineGlobal Security Policieson the Global Manager (Option B). When a security group or a Distributed Firewall (DFW) rule is created on the GM, it is automatically synchronized to all registered Local Managers. This ensures that a "Finance App" security policy is identical in AZ1 and AZ2. These global objects are identified by a specific tag in the local NSX Manager UI, indicating they are managed globally and cannot be modified locally.
Furthermore, NSX handles the coexistence of global and local rules through a specific evaluation order (Option D). In the NSX DFW category structure,Global Categories(managed by the GM) are evaluated beforeLocal Categories(managed by the LM). This ensures that corporate-wide security mandates (like
"Block All SSH to Management") defined at the GM level are enforced first and cannot be bypassed by localized site-level rules.
Option A is incorrect because manual naming consistency is prone to error and does not provide actual synchronization. Option C and E are incorrect as they contradict the fundamental purpose of Federation, which is to centralize management and automate synchronization to prevent configuration drift and security gaps. Therefore, defining policies on the GM and utilizing the inherent precedence of global rules is the verified design best practice for VCF Federation.
NEW QUESTION # 38
An administrator implements route leaking between the Tier-0 gateways to enhance east/west communication because the physical L3 devices are oversubscribed.
Where should route-maps be configured based on the architecture observed in the diagram?
Answer:
Explanation:
Explanation:
The administrator should click on theblue box representing the logical link between the two Tier-0 Gateways.
In the multi-tenant architecture ofVMware Cloud Foundation (VCF) 9.0, networking is structured hierarchically with VPC Gateways, Transit Gateways, and Tier-0 Gateways. Under normal conditions, traffic between isolated divisions (such as Division A and Division B) that need to communicate might be routed
"North" all the way to thePhysical L3 Devices(the physical core routers) before being routed back down.
However, if these physical devices are oversubscribed or reaching their throughput limits, this creates a performance bottleneck.
To optimize this flow, NSX allows forRoute Leakingat the Tier-0 layer. By establishing a logical peering or connection directly between twoTier-0 Gatewayswithin the virtual fabric, administrators can exchange routing information (prefixes) between the two environments without the traffic ever leaving the SDDC.
To control exactly which networks are shared and to prevent routing loops or unauthorized access,Route- Mapsmust be applied at this inter-gateway connection point. These route-maps define the "Permit" or "Deny" statements for specific IP prefixes being "leaked" from one routing table to another. By clicking the highlighted link between the Tier-0 Gateways, the administrator is targeting the specific control plane interface where these prefix exchanges occur. This configuration ensures that East-West traffic between Division A and Division B is handled locally by theNSX Edge Nodes, effectively bypassing the oversubscribed physical L3 devices and significantly reducing latency and physical network congestion.
NEW QUESTION # 39
An administrator must provide North/South connectivity for a VPC. The fabric exposes a distributed external VLAN across all ESX hosts. But, the only BGP peer to the core is on a VLAN only accessible on the Edge Cluster. Which design is required?
- A. Distributed Transit Gateway with an EVPN route reflector on the transport nodes.
- B. Deploy a Provider Tier-1 with BGP and connect the VPC Transit Gateway via route leaking.
- C. Centralized Transit Gateway on the Edge Cluster.
- D. Use a VPC Tier-0 Gateway in active/active mode with distributed eBGP peering.
Answer: C
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In aVMware Cloud Foundation (VCF)environment utilizing theVirtual Private Cloud (VPC)model, North
/South connectivity is managed by theTransit Gateway (TGW). The TGW acts as the bridge between the VPC-internal networks and the provider-level physical network.
The scenario presents a specific constraint: while an external VLAN exists across all hosts, the actual BGP peering point (the interface to the physical core routers) is restricted to theNSX Edge Cluster. In NSX terminology, when a gateway or service must be anchored to specific Edge Nodes to access physical network services-such as BGP peering, NAT, or stateful firewalls-it must be configured as aCentralizedcomponent.
ACentralized Transit Gateway(Option C) is instantiated on the Edge nodes. This allows the TGW to participate in the BGP session with the core routers on the VLAN that is only accessible to those Edges. The TGW then handles the routing for the VPC's internal segments. Traffic from the ESXi transport nodes (East- West) travels via the Geneve overlay to the Edge nodes, where it is then routed North-South by the Centralized TGW using the physical BGP peer.
Option A is incorrect because "distributed eBGP peering" would require every ESXi host to have peering capabilities, which contradicts the constraint. Option B involves EVPN, which is a significantly more complex and different architecture than what is required for standard VPC North/South access. Option D is an unnecessarily complex routing design that is not the standard VCF/VPC implementation pattern. Thus, the use of a Centralized Transit Gateway on the Edge cluster is the verified design requirement to bridge the gap between the overlay VPC and the localized BGP peering point.
NEW QUESTION # 40
An administrator is tasked to configure NSX Federation between separate VMware Cloud Foundation (VCF) Fleets. Which requirement must all sites meet before being added to a Global Manager (GM) for NSX Federation?
- A. All Sites must use the same VTEP VLAN and IP pools.
- B. All sites must be managed by the same VCF instance.
- C. All sites must use identical Tier-0 gateway BGP autonomous system numbers.
- D. All sites must have the same NSX version and build.
Answer: D
NEW QUESTION # 41
An administrator is tasked to enable users to configure an individual VPC, but not create subnets. What three NSX roles would the administrator assign to allow access without the ability to create subnets? (Choose three.)
- A. Security Admin
- B. VPC Admin
- C. Security Operator
- D. Network Operator
- E. Network Admin
Answer: B,C,D
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
With the introduction of theVirtual Private Cloud (VPC)consumption model inVCF 9.0and late 5.x releases, Role-Based Access Control (RBAC) has become more granular to support true multi-tenancy. A VPC is designed to be a self-contained "container" for a department's or user's networking resources.
To meet the specific requirement where a user can configure aspects of an individual VPC but is restricted from creating new subnets (which involves modifying the underlying network CIDR blocks and IPAM), a combination of specific roles is required.
* VPC Admin:This is the primary role for the user within their assigned VPC. It allows the user to manage the overall VPC environment, including high-level settings and monitoring. However, the VPC Admin's power is often limited by the specific quotas and policies set by the Enterprise Admin.
* Security Operator:This role allows the user to view security configurations and policies without having the permission to modify the network fabric or create new infrastructure components like subnets. It provides the "read-only" visibility into the security posture of the VPC.
* Network Operator:Similar to the Security Operator, the Network Operator role provides visibility into the networking state-such as routing tables, segment status, and connectivity-without granting the
"Write" permissions required to provision new subnets or alter the network topology.
AssigningNetwork Admin(Option B) orSecurity Admin(Option A) would grant too much privilege, as these roles typically include the ability to create, delete, and modify subnets and firewall policies at a structural level. By combining theVPC Adminrole withOperator-level roles, the administrator ensures the user has the necessary context to manage their assigned resources while strictly adhering to the restriction against creating new network subnets.
NEW QUESTION # 42
An administrator has a vSphere 8 Update 1a with NSX 4.1.0.2 environment. What option can the administrator use to converge this vSphere with NSX environment into a VMware Cloud Foundation (VCF) Workload Domain?
- A. Upgrade the environment and use VCF Operations to converge the vSphere environment into a new VCF Workload Domain.
- B. Upgrade NSX to version 9 into the vSphere 8 environment and use the VCF installer to converge the vSphere 8 with NSX environment into a new VCF Workload Domain.
- C. Use the VCF installer to automatically converge the vSphere with NSX environment into a new VCF Workload Domain.
- D. Upgrade the environment version and use the VCF installer to converge the vSphere environment into a new VCF Workload Domain.
Answer: C
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
The process of transforming an existing, "brownfield" environment into a VCF-managed infrastructure is known asConvergence. In VCF 5.x and the advancements found in VCF 9.0, VMware provides theVCF Import Tool(often bundled or utilized alongside the VCF Installer/Cloud Builder) specifically for this purpose.
An environment runningvSphere 8 Update 1aandNSX 4.1.0.2is within the supported compatibility matrix for VCF 5.x convergence. The most direct and verified method (Option A) is to use theVCF Installerto "ingest" the existing vCenter and NSX Manager. During this process, the installer validates the current configuration, ensures the hosts are compatible, and then brings them under the management of a newly deployedSDDC Manager.
One of the significant advantages of this approach is that it avoids the need for a "rip and replace" of the existing networking. The VCF Installer identifies the existing NSX Manager and the logical networking constructs. Once the convergence is successful, the environment is treated as a standardVCF Workload Domain.
Options B and C are incorrect because VCF's design principle is to perform the convergence at a known stable and compatible versionbeforeusing the SDDC Manager'sLifecycle Management (LCM)to perform upgrades. Manually upgrading to version 9 prior to convergence can introduce configuration drifts that the VCF Installer may not be able to reconcile. Option D is incorrect asVCF Operations(formerly vRealize Operations) is a monitoring and optimization tool; it does not have the administrative capability to perform the structural convergence of the SDDC stack. Therefore, the automated convergence via the VCF Installer is the correct architectural path.
NEW QUESTION # 43
A sovereign cloud provider has a VMware Cloud Foundation (VCF) stretched Workload Domain across two data centers (AZ1 and AZ2), where site connectivity via Layer 3 is provided by the underlay. The following NSX details are included in the design:
* Each site must host its own local NSX Edge Cluster for availability zones.
* Tier-0 gateways must be configured in active/active mode with BGP ECMP to local top-of-rack switches.
* Inter-site Edge TEP traffic must not cross the inter-DC link.
* SDDC Manager is used to automate NSX deployment.
During deployment of the Edge Cluster for AZ2, the SDDC Manager workflow fails because the Edge transport nodes' TEP IPs are not reachable from the ESXi transport nodes. Which step ensures correct Edge Cluster deployment in multi-site stretched domains?
- A. Configure BGP neighbors before deploying the Edge Cluster.
- B. Create an AZ2-specific Edge TEP IP pool and map it to the AZ2 uplink profile before deploying the Edge Cluster.
- C. Disable the liveness check during Edge deployment in SDDC Manager.
- D. Reuse the TEP IP pool from AZ1.
Answer: B
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In aVMware Cloud Foundation (VCF)stretched cluster or Multi-Availability Zone (Multi-AZ) architecture, the networking design must account for the fact that AZ1 and AZ2 typically reside in different Layer 3 subnets. While the NSX Overlay provides Layer 2 adjacency for virtual machines across sites, the underlying Tunnel Endpoints (TEPs)must be able to communicate over the physical Layer 3 network.
According to the VCF Design Guide for Multi-AZ deployments, when stretching a workload domain, each availability zone should have its own dedicatedTEP IP Pool. This is because TEP traffic is encapsulated (Geneve) and routed via the physical underlay. If the Edge nodes in AZ2 were to use the same IP pool as AZ1 (Option C), the physical routers would likely encounter routing conflicts or reachability issues, as the subnet for AZ1 would not be natively routable or "local" to the AZ2 Top-of-Rack (ToR) switches.
The failure during the SDDC Manager workflow occurs because the automated "Liveness Check" or "Pre- validation" step attempts to verify that the newly assigned TEP IPs in AZ2 can reach the existing TEPs in the environment. To resolve this and ensure a successful deployment, the administrator must define a uniqueAZ2- specific IP Poolin NSX. Furthermore, this pool must be associated with anUplink Profile(or a Sub-Transport Node Profile in VCF 5.x/9.0) that uses the specific VLAN tagged for TEP traffic in the second data center.
This ensures that the Edge Nodes in AZ2 are assigned IPs that are valid and routable within the AZ2 underlay, allowing Geneve tunnels to establish correctly to the ESXi hosts in both sites without requiring a stretched Layer 2 physical network for the TEP infrastructure.
NEW QUESTION # 44
The administrator must configure Border Gateway Protocol (BGP) on the Tier-0 Gateway to establish neighbor relationships with upstream routers. Which two statements describe the Border Gateway Routing Protocol (BGP) configuration on a Tier-0 Gateway? (Choose two.)
- A. The network is divided into areas that are logical groups.
- B. EIGRP is configured by default.
- C. It supports a 4-byte autonomous system number.
- D. Can be used as an Exterior Gateway Protocol.
Answer: C,D
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In the architecture ofVMware Cloud Foundation (VCF)and its networking component, NSX, theTier-0 Gatewayserves as the critical demarcation point between the virtualized overlay network and the physical infrastructure. To facilitate this communication, BGP is the industry-standard protocol utilized.
BGP is fundamentally designed as anExterior Gateway Protocol (EGP). While it can be used internally (iBGP), its primary role in a VCF deployment is to exchange routing information between the SDDC and the physical Top-of-Rack (ToR) switches or core routers (eBGP). This allows the physical network to learn about the virtual subnets (overlay segments) and allows the virtual environment to receive a default route or specific external prefixes. This confirms that BGP is utilized as an EGP in these designs.
Furthermore, as global IP networking has evolved, the traditional 2-byte Autonomous System (AS) numbers (ranging from 1 to 65,535) were found to be insufficient for the number of organizations requiring them.
Modern NSX versions integrated into VCF 5.x and 9.0 fully support4-byte Autonomous System numbers (ranging from 1 to 4,294,967,295). This support is essential for service providers and large enterprises that have been assigned 4-byte ASNs by regional internet registries.
Option A is incorrect because EIGRP is a proprietary Cisco protocol and is not used by NSX. Option C describes OSPF (Open Shortest Path First), which uses "Areas," whereas BGP uses "Autonomous Systems." Therefore, the ability to act as an EGP and support for 4-byte ASNs are the verified characteristics of BGP within the VCF networking stack.
NEW QUESTION # 45
An administrator is troubleshooting the packet flow of an incoming response to an ICMP Reply payload destined for 10.1.1.10 in the diagram.
The packet arrived at the Tier-0 SR at 172.16.215.100/29.
Which highlighted location identifies the next hop in the path to the destination?
Answer:
Explanation:
Explanation:
the administrator should click theTier-1 DR iconlocated within theEdge Node.
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:In aVMware Cloud Foundation (VCF)environment, North-South traffic flows through a hierarchical routing structure composed ofTier-0andTier-1 Gateways. Each gateway is further divided into a Distributed Router (DR)component, which runs as a kernel module on all Transport Nodes (ESXi and Edges), and aService Router (SR), which provides centralized services and resides on the Edge Nodes.
According to the packet walk logic for an incoming (North-to-South) packet, once the traffic arrives from the physical router at theTier-0 Service Router (SR)on the Edge Node, it must be routed toward the destination virtual machine (10.1.1.10). In a multi-tier NSX architecture, the Tier-0 SR identifies that the destination subnet belongs to a connectedTier-1 Gateway. The communication between the Tier-0 and Tier-1 gateways occurs over an internal transit subnet, often referred to as theRouter Link(in this diagram, represented by the
100.64.16.0/31 subnet).
The "Next Hop" for the packet currently residing at the Tier-0 SR on the Edge Node is theTier-1 Distributed Router (DR)instance located on that same Edge Node. This is because the Edge Node participates as a Transport Node in the overlay and maintains local instances of all Distributed Routers to ensure efficient path processing. After the packet is processed by the local Tier-1 DR on the Edge Node, it determines that the destination VM is residing on a remote host (Compute Hypervisor). Only then is the packet encapsulated in a Geneveheader and sent via theTunnel Endpoints (TEP)from the Edge Node (172.16.215.124) to the Compute Hypervisor (172.16.215.67). Therefore, the Tier-1 DR on the Edge Node is the immediate logical next step in the routing pipeline before any host-to-host encapsulation occurs.
NEW QUESTION # 46
An administrator is responsible for managing a VMware Cloud Foundation (VCF) Private Cloud consisting of a single VCF Fleet with a single Workload Domain.
The administrator has been tasked with configuring NSX to support the new Virtual Desktop Infrastructure (VDI) solution that allows users to securely access a mainframe- based application located on the physical network. The VDI solution will use a dedicate DHCP solution for each of the the desktop pool segments and static addresses for all VDI management components.
The administrator completes the following steps towards configuring DHCP:
1. Creates a new tier-1 gateway (vdi-tier-1) and links it to the tier-0 gateway (gw-tier-0).
2. Creates one new segment for vdi management (vdi-seg-01) and connects it to vdi-tier-1.
3. Creates two new segments for virtual desktops (vdi-seg-02 and vdi-seg-03) and connects them to vdi-tier-1.
Drag and drop the six steps from the list of Possible Steps on the left and place them in order in to the Solution Steps. (Choose six.)
Answer:
Explanation:
Explanation:
For the VDI solution requiring dedicated DHCP for desktop pool segments and static addresses for management components, the correct sequence of steps to configure DHCP is as follows:
* Set the DHCP Config on vdi-tier-1 to DHCP Server and attach a new DHCP Server Profile with an IPv4 DHCP Server Address.This establishes the Tier-1 gateway as the local DHCP service provider for its attached segments.
* On vdi-seg-02, in the DHCP Config set the DHCP Type to Gateway DHCP Server.This instructs the segment to use the DHCP server service configured on its parent Tier-1 gateway.
* On vdi-seg-02, in the DHCP Config set the DHCP Range and DNS Servers.Defines the specific IP pool and network settings for the first desktop pool.
* On vdi-seg-03, in the DHCP Config set the DHCP Type to Gateway DHCP Server.Instructs the second desktop segment to also leverage the Tier-1 DHCP service.
* On vdi-seg-03, in the DHCP Config set the DHCP Range and DNS Servers.Defines the IP pool for the second desktop pool.
* On vdi-seg-01, in the DHCP Config set the DHCP Type to DHCP Relay.Since management components use static addresses provided by an external mainframe-based solution or dedicated physical infrastructure, a relay is used rather than a local server to ensure proper network isolation and policy enforcement for the physical mainframe application.
NEW QUESTION # 47
An administrator is configuring NSX resource sharing to allow shared access to multiple resources in the default space.
By default, which user role owns the shared resources for the default space?
- A. Security Admin
- B. Project Admin
- C. Enterprise Admin
- D. Network Admin
Answer: C
Explanation:
In NSX Multi-Tenancy (Projects), theEnterprise Adminacts as the provider-level administrator who owns global objects in the default space. This ensures central control over resources that are shared across different projects.
NEW QUESTION # 48
An administrator is preparing to deploy a new workload domain that will host vSphere Kubernetes Service (VKS) clusters. Before configuring the network for the Kubernetes clusters, the administrator needs to create a Tier-0 Gateway to handle North/South connectivity. What is the requirement for creating a Tier-0 Gateway for use with a workload domain that is running the vSphere Kubernetes service (VKS) with VPC?
- A. The Tier-0 Gateway must have IPv6 enabled.
- B. The Tier-0 Gateway must be configured in Active/Standby mode.
- C. The Tier-0 Gateway route map must contain an IP prefix with only a deny rule.
- D. The Tier-0 Gateway must be configured in Non-Preemptive failover mode.
Answer: B
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
When deployingvSphere Kubernetes Service (VKS)-often referred to as Tanzu with VCF-within a Virtual Private Cloud (VPC)consumption model, the networking requirements are more stringent than a standard VM-only environment. This is because VKS relies on stateful services such asLoad Balancing(via the NSX Advanced Load Balancer or the native NSX LB) andNATto provide ingress and egress for Kubernetes pods and services.
In NSX architecture, any gateway that providesstateful servicesmust be configured inActive/Standbymode.
While an Active/Active Tier-0 gateway is excellent for high-throughput ECMP routing, it cannot support stateful features because return traffic might arrive at the "Standby" (or alternative Active) node which does not share the same session state table, resulting in dropped connections.
Specifically, for VKS clusters integrated with the VPC model in VCF 5.x and 9.0, the Tier-0 gateway acts as the provider-side gateway. To ensure that the KubernetesLoadBalancerservice types andSNAT/DNATfor pods function correctly and maintain session persistence, the gateway must be anchored to a specific Service Router (SR) on an Edge node. This is only possible in anActive/Standbyconfiguration.
Option B (Non-Preemptive) is a failoversettingbut not the primary architectural requirement. Option D (IPv6) may be used depending on the specific network design, but it is not a mandatory requirement for VKS functionality. Option A is incorrect as route maps usually require "Permit" rules to actually function. Thus, the verified architectural prerequisite for a VKS/VPC-enabled workload domain is anActive/Standby Tier-0 Gateway.
NEW QUESTION # 49
An administrator has a VMware Cloud Foundation (VCF) instance. A critical NSX security update has been released by Broadcom. How can the administrator install the NSX update?
- A. Download the NSX patch to VCF Operations. Apply it using VCF Operations Fleet Management.
- B. Download the NSX patch to the NSX Manager. Apply it using VCF Operations Fleet Management.
- C. Download the NSX patch to VCF Operations. Apply it using NSX Manager.
- D. Download the NSX patch to the NSX Manager. Apply it using NSX Manager.
Answer: A
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In the unified architecture ofVMware Cloud Foundation (VCF) 9.0, the management paradigm has shifted towards a more centralized "Fleet Management" approach. Historically, in VCF 4.x and 5.x, updates were primarily managed via the SDDC Manager using the Lifecycle Management (LCM) engine. However, with the integration advancements in version 9.0,VCF Operations(formerly part of the Aria/vRealize suite) has taken on a more direct role in the orchestration of updates across the entire VCF "Fleet." To comply with the VCF operational model, administrators no longer apply patches directly within the component managers (like NSX Manager or vCenter) if they wish to remain within the supported, automated framework. Instead, the workflow begins by downloading the bundle or patch toVCF Operations. This ensures that the update is validated against the currentBill of Materials (BOM)and that all dependencies- such as compatibility with the underlying ESXi versions or the management vCenter-are checked before any changes are committed.
Once the patch is available in VCF Operations, the administrator utilizesFleet Managementto apply it. This service orchestrates the update across all NSX Managers and Transport Nodes (Edges and Hosts) in a controlled, non-disruptive manner. If the administrator were to apply the patch directly in NSX Manager (Option D), the SDDC Manager and VCF Operations databases would go out of sync, leading to a
"configuration drift" where the system no longer knows which version is actually running, potentially breaking future automated lifecycle tasks. Therefore, the centralized download and application throughVCF Operations Fleet Managementis the verified procedure for maintaining a healthy and compliant VCF 9.0 environment.
NEW QUESTION # 50
An administrator is investigating packet loss reported by workloads connected to VLAN segments in an NSX environment. Initial checks confirm:
* All VMs are powered on
* VLAN segment IDs are consistent across transport nodes
* Physical switch configurations are correct.
Which two NSX tools can be used to troubleshoot packet loss on VLAN Segments? (Choose two.)
- A. Packet Capture
- B. Live Flow
- C. Traceflow
- D. Activity Monitoring
- E. Flow Monitoring
Answer: A,C
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In a VMware Cloud Foundation (VCF) environment, troubleshooting packet loss requires tools that can provide visibility into both the logical and physical paths of a packet. When dealing specifically withVLAN segments(as opposed to Overlay segments), the traffic does not leave the host encapsulated in Geneve; instead, it is tagged with a standard 802.1Q header.
Traceflowis the primary diagnostic tool within NSX for identifying where a packet is being dropped. It allows an administrator to inject a synthetic packet into the data plane from a source (such as a VM vNIC) to a destination. The tool then reports back every "observation point" along the path, including switching, routing, and firewalling. If a packet is dropped by a Distributed Firewall (DFW) rule or a physical misconfiguration that wasn't caught initially, Traceflow will explicitly state at which stage the packet was lost.
Packet Captureis the second essential tool. NSX provides a robust, distributed packet capture utility that can be executed from the NSX Manager CLI or UI. This tool allows administrators to capture traffic at various points, such as the vNIC, the switch port, or the physical uplink (vmnic) of the ESXi Transport Node. By comparing captures from different points, an administrator can determine if a packet is reaching the virtual switch but failing to exit the physical NIC, or if return traffic is reaching the host but not the VM.
Options likeFlow MonitoringandLive Floware excellent for observing traffic patterns and session statistics (IPFIX), but they are less effective for pinpointing the exact cause of "packet loss" compared to the granular, packet-level analysis provided by Traceflow and Packet Capture.Activity Monitoringis typically used for endpoint introspection and user-level activity, which is irrelevant to Layer 2/3 packet loss troubleshooting.
NEW QUESTION # 51
A cloud service provider runs VPCs with differing traffic patterns:
* Some VPCs are generating high, large North/South flows.
* Most of the VPCs generate very little traffic.
The architect needs to optimize Edge dataplane resource consumption while ensuring that noisyVPCs do not impact others.
Which optimization satisfies the requirement?
- A. Reduce the number of VPCs by consolidating VPCs into shared namespaces.
- B. Convert high-traffic VPCs into VLAN-backed segments attached directly to Tier-0 gateways.
- C. Use multiple Edge clusters and distribute VRF-backed VPCs based on traffic profiles.
- D. Assign one dedicated Edge node per high-traffic VPC.
Answer: C
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In a VMware Cloud Foundation (VCF) environment, especially with the architectural evolution in VCF 9.0, theVirtual Private Cloud (VPC)model is the primary way to deliver self-service, isolated networking. The networking performance for North/South traffic-traffic leaving the SDDC for the physical network-is processed byNSX Edge Nodes. These Edge Nodes use DPDK (Data Plane Development Kit) to provide high- performance packet processing, but their resources (CPU and Memory) are finite.
When dealing with "noisy neighbors"-tenants or VPCs that consume a disproportionate amount of throughput-it is critical to isolate their data plane impact. According to the VMware Validated Solutions and VCF Design Guides, the most scalable and efficient way to achieve this is through the use ofMultiple Edge Clusters. By creating distinct Edge clusters, an architect can physically isolate the compute resources used for routing.
In this scenario, high-traffic VPCs can be backed by specificVRF (Virtual Routing and Forwarding) instances on a Tier-0 gateway that is hosted on a dedicated high-performance Edge Cluster. Meanwhile, the numerous low-traffic VPCs can share a different Edge Cluster. This "Traffic Profile" based distribution ensures that a spike in traffic within a "heavy" VPC only consumes the DPDK cycles of its assigned Edge nodes, leaving the resources for the "quiet" VPCs untouched.
Option A is incorrect because Edge nodes function in clusters for high availability; assigning a single node creates a single point of failure and is administratively heavy. Option B reduces the multi-tenancy benefits and doesn't solve the resource contention at the Edge level. Option C removes the benefits of the software- defined overlay and VPC consumption model. Therefore, distributingVRF-backed VPCsacross multiple Edge clusters based on their expected load is the verified design best practice for optimizing resource consumption while maintaining strict performance isolation in a VCF provider environment.
NEW QUESTION # 52
An administrator needs to prevent the datacenter from advertising any internal prefixes toward a new VPC, while still ensuring the VPC receives a default route learned from the datacenter's upstream network. Where should the routing policy be applied?
- A. On the provider Tier-0 neighbor.
- B. On the VPC transit gateway.
- C. On the Tier-1 gateway.
- D. On each segment default gateway.
Answer: B
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In theVMware Cloud Foundation (VCF) 9.0andNSX VPCarchitecture, theTransit Gateway (TGW)is the central routing element that interconnects VPCs to each other and to the provider's infrastructure (Tier-0 or VRF gateways). It acts as the "Project-level" gateway that aggregates North-South traffic.
To control the visibility of routes within a specific VPC, the administrator must utilizeRoute Filteringat the VPC's boundary. When a VPC is attached to a Transit Gateway, a logical interface is created. To prevent the data center's internal prefixes (such as management networks or other tenant subnets) from being seen by the VPC while still providing a path to the internet, a prefix list or route map should be applied to theVPC Transit Gateway. This policy will explicitly "Deny" specific internal CIDR ranges while "Permitting" the
$0.0.0.0/0$ default route advertisement from the provider.
Applying the policy at theTier-1 gateway(Option B) is technically similar but in the VPC model, the "Tier-1" is often an obscured or automated component of the VPC itself; the Transit Gateway is the designed administrative point for inter-project and North-South policy enforcement. Applying it at theprovider Tier-0 neighbor(Option D) would be too global, affecting all VPCs or projects connected to that Tier-0, rather than the "new VPC" specifically. Therefore, the Transit Gateway provides the necessary granular control for multi- tenant isolation and routing optimization as per the VCF 9.0 networking model.
NEW QUESTION # 53
An administrator is responsible for a VMware Cloud Foundation (VCF) Private Cloud. The administrator has been tasked with identifying why there is no data ingress into a workload domain.
The workload domain has been configured with:
. A dedicated NSX Edge Cluster.
. A Tier 0 gateway.
. A Tier-1 gateway that is configured for Distributed Routing only.
. An NSX segment where a test virtual machine is located.
As part of the exercise, the administrator must map the traffic flow for data ingress into the workload domain to identify the steps that external network traffic will take to ingress into the workload domain and reach the virtual machine.
Drag and drop the six steps from the Steps list on the right and place them in order in the Solution Steps.
(Choose six.)
Answer:
Explanation:
Explanation:
To identify why there is no data ingress into a workload domain, an administrator must understand the specific path external traffic takes. For a workload domain configured with a Tier-0 gateway and a Tier-1 gateway (Distributed Routing only), the ingress traffic flow follows a hierarchical path from the physical network through the NSX logical components to the virtual machine.
Ingress Traffic Flow Sequence
The correct sequence of steps for external network traffic to ingress the workload domain and reach the virtual machine is as follows:
* Uplink for the Tier-0 Service Router (SR): Traffic enters the NSX environment from the physical network through the physical-to-logical interface on the Edge node.
* Inter-Tier interface of the Distributed Router (DR) of the Tier-0 gateway: After being received by the Service Router, the packet is routed internally within the Tier-0 gateway to its distributed component.
* Inter-tier interface of the Distributed Router (DR) on the Tier-1 gateway TEP on the Edge: The Tier-0 gateway routes the packet to the Tier-1 gateway. In this specific scenario, since the Tier-1 is
"Distributed Routing only," this logical transition occurs on the Edge node participating in the transport zone.
* TEP on the destination host: The Edge node encapsulates the packet (typically via Geneve) and tunnels it across the physical fabric to the specific ESXi host where the target virtual machine is currently residing.
* Downlink interface of the Tier-1 Distributed Router (DR) to the segment to which the workload VM is attached: On the destination host, the packet is de-encapsulated. The local Tier-1 DR instance identifies the correct logical segment (VNI) for the destination IP.
* NSX portgroup representing the destination segment on the destination host dvfilter and vNic of the workload VM: The packet is delivered to the virtual switch port, passes through any applied Distributed Firewall (dvfilter) rules, and finally reaches the virtual machine's network interface card (vNIC).
NEW QUESTION # 54
An administrator is attempting to confirm the successful transmission between an internal VM to an external destination.
An ICMP request packet is being sent from Sa-transit-web-01 to the Student Desktop in the diagram.
Drag and Drop the commands output into their appropriate originating NSX object.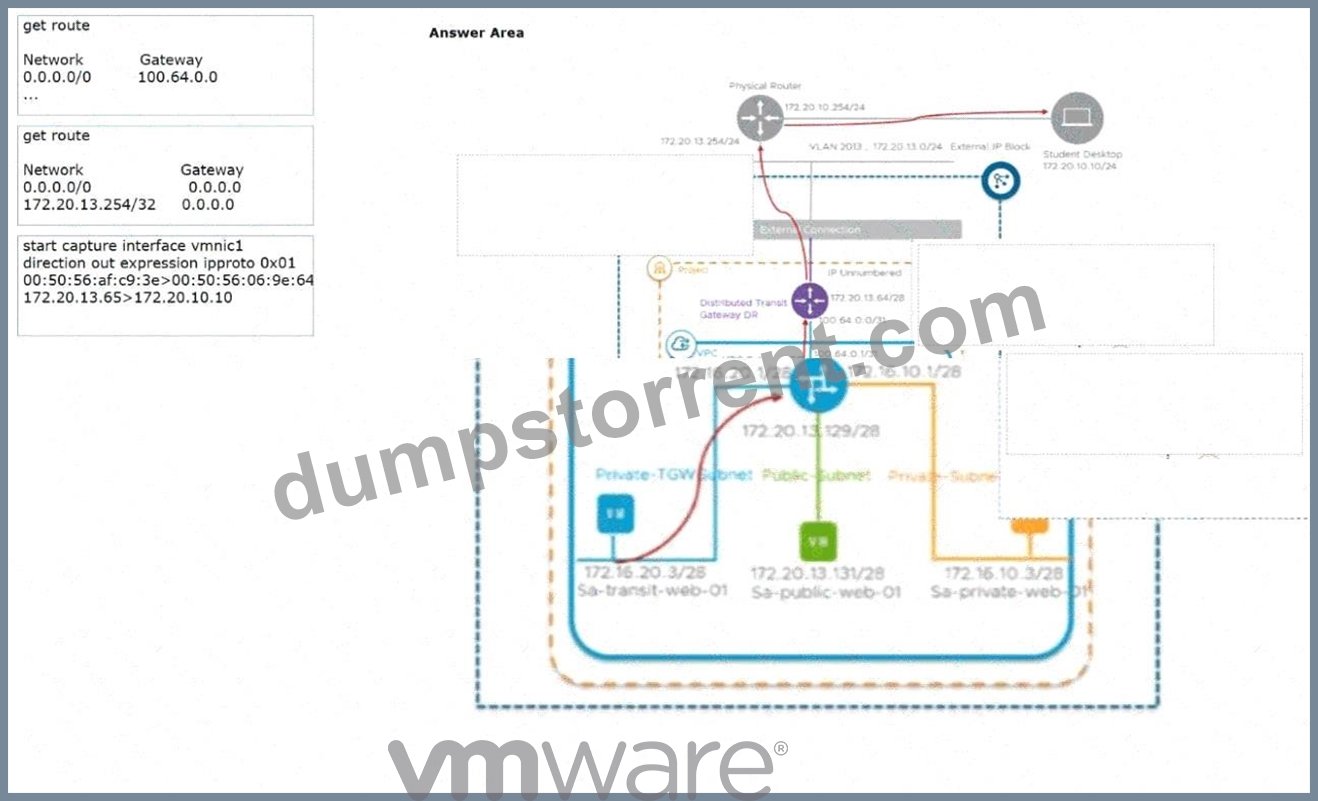
Answer:
Explanation: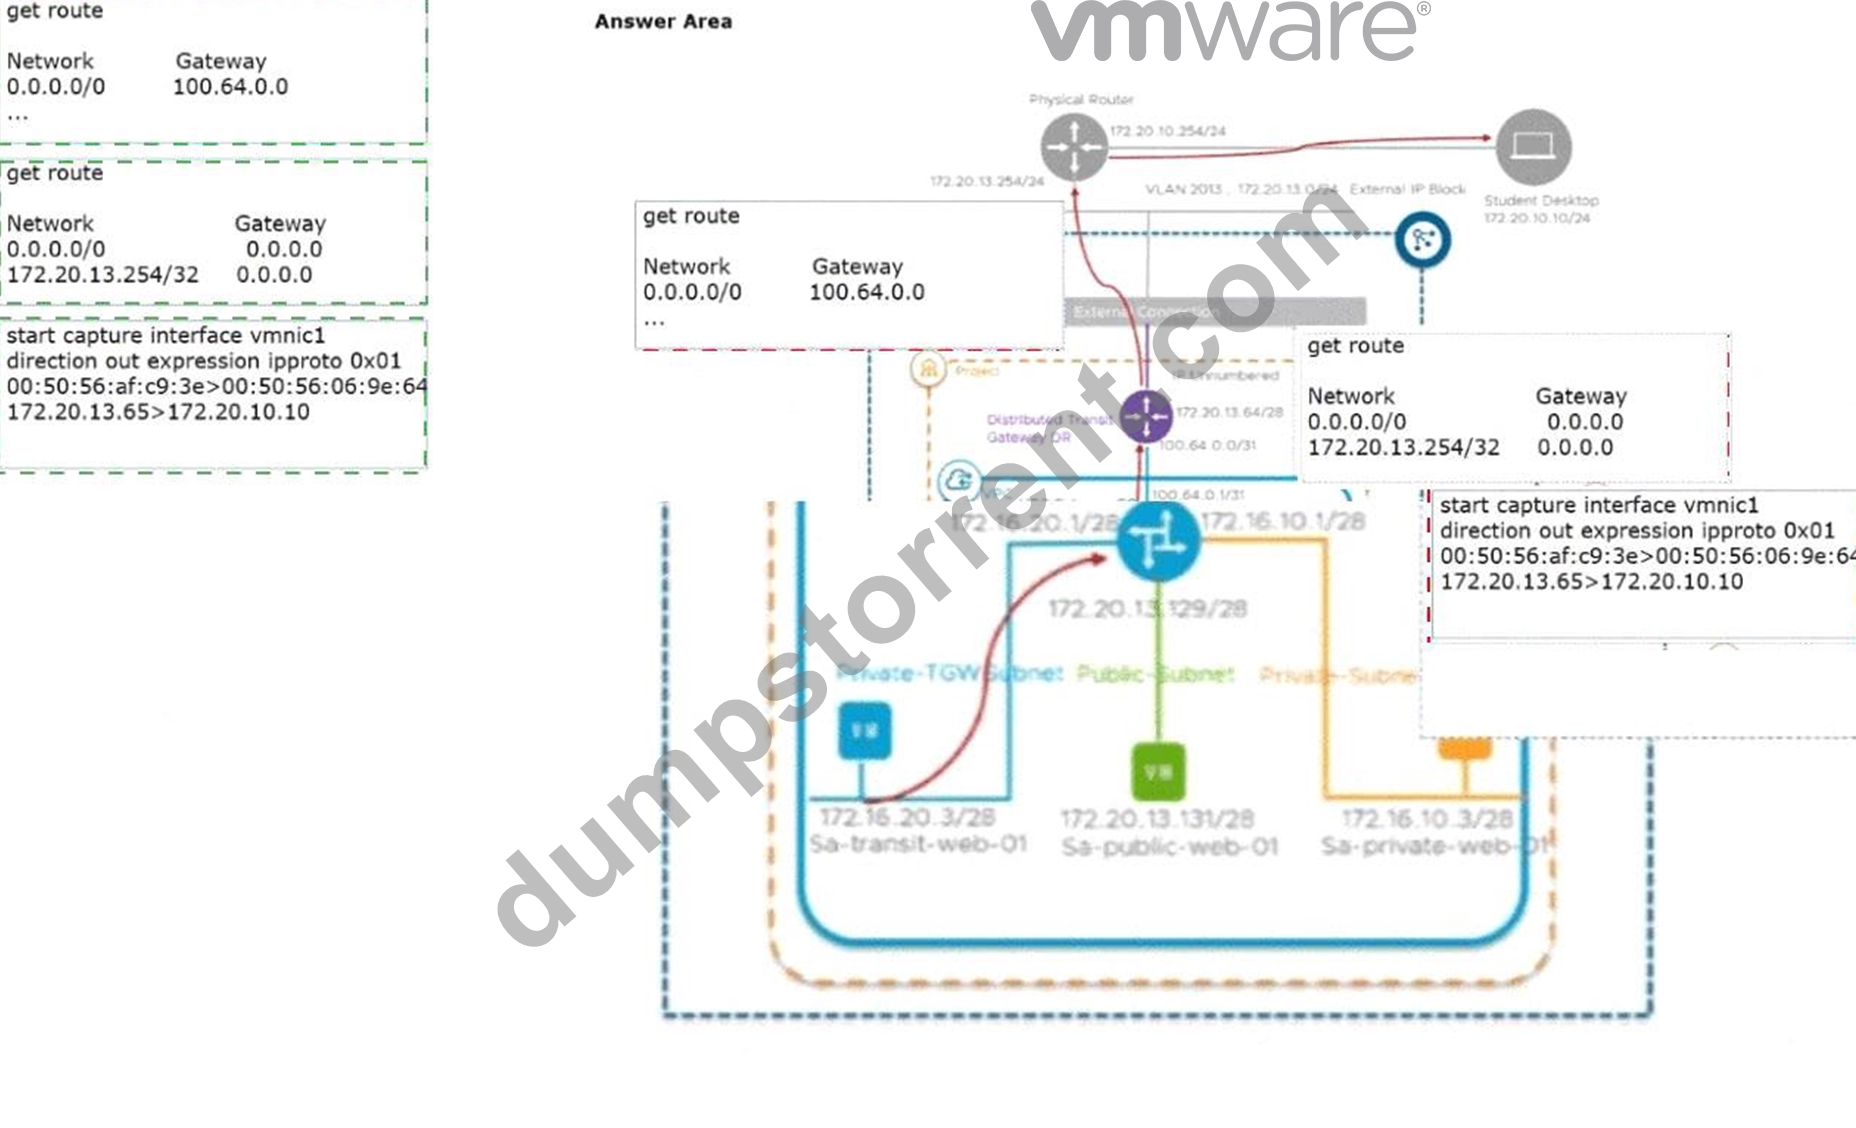
Explanation: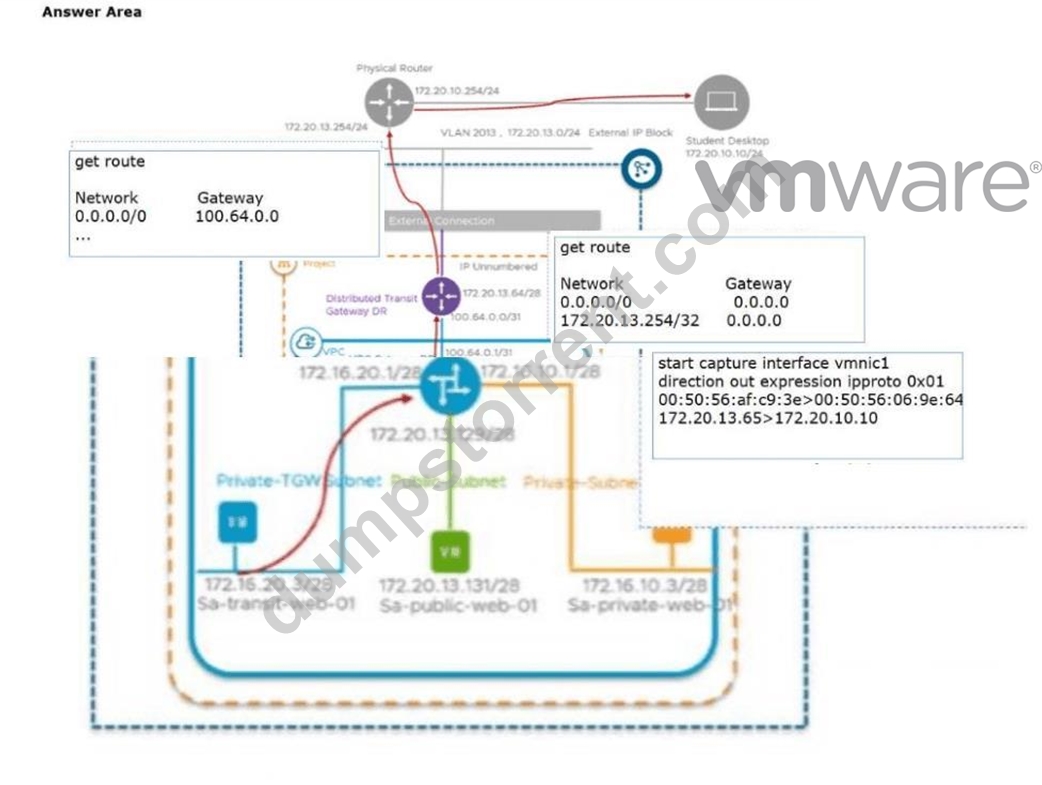
In a modernVCF 9.0environment using theVirtual Private Cloud (VPC)model, North-South traffic follows a specific hierarchical path. When a VM, such asSa-transit-web-01, initiates an ICMP request to an external destination (the Student Desktop), the packet must traverse the VPC's internal routing before exiting to the physical network.
The first hop is theVPC Tier-1 Gateway. This gateway manages the localized subnets within the VPC. In this architecture, the VPC Tier-1 is typically configured with a default route ($0.0.0.0/0$) pointing to the Transit Gateway (TGW). The gateway address 100.64.0.0 represents the provider-side interface of the Router Link connecting the VPC to the Transit Gateway. Thus, the command output showing the default route to 100.64.0.0 belongs to the VPC Gateway.
The second hop is theDistributed Transit Gateway DR. The Transit Gateway acts as the aggregation point for multiple VPCs and provides the bridge to the physical datacenter fabric. The command output for this object shows a default route with a gateway of 0.0.0.0, indicating it is directly peered or using a specific unnumbered interface to reach the physical router. Additionally, it identifies the specific physical router IP (172.20.13.254/32) as a known local next-hop, which is a common characteristic of the Transit Gateway's forwarding table when performing North-South transitions.
Finally, theTransport Node (ESXi Host)is where the physical packet capture occurs. As the packet exits the virtual environment, it is placed on a physical uplink (vmnic1). The packet capture output confirms the transformation of the traffic: it shows the source IP of the VM (or its translated NAT address 172.20.13.65) reaching out to the destination 172.20.10.10. The inclusion of ipproto 0x01 (ICMP) and the specific MAC addresses confirms that the packet has successfully traversed the NSX overlay and is now a standard Ethernet frame on the physical wire.
NEW QUESTION # 55
An NSX Manager cluster has failed. The administrator deployed a new NSX Manager using the latest version and attempted to restore from a backup, but the restore operation failed. What would an administrator do to recover the cluster?
- A. Use the NSX restore API instead of the UI.
- B. Use SDDC Manager to replace NSX Manager.
- C. Deploy an NSX Manager that matches the backup's build.
- D. Edit the backup passphrase to match the new build.
Answer: C
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
A critical requirement for the backup and restore process inVMware NSX(and by extension, VCF) is version parity. The NSX Manager backup contains the database schema, configuration files, and state information specific to the version of the software that was running at the time the backup was taken.
When performing a restore into a "clean" environment, the NSX documentation explicitly states that the target NSX Manager appliancemust be of the exact same build versionas the appliance that generated the backup.
If an administrator attempts to restore a backup from version 4.1.x onto a newly deployed manager running version 4.2.x or 9.0 (as implies by "latest version"), the restore process will fail because the database schema of the newer version is incompatible with the older data structure.
In aVCF environment, whileSDDC Manager(Option B) handles the lifecycle and replacement of failed nodes, the actual "Restore from Backup" workflow is an NSX-native operation. If the entire cluster is lost, the recovery procedure involves:
* Identifying the build number from the backup metadata.
* Deploying a single "Discovery" node of that exact build.
* Pointing that node to the backup repository (SFTP/FTP).
* Executing the restore.
Once the primary node is restored to the correct version, the administrator can then add additional nodes to reform the cluster. Attempting to use the API (Option C) or changing the passphrase (Option A) will not bypass the fundamental requirement for version alignment between the backup file and the installed binary.
NEW QUESTION # 56
......
Get Latest 3V0-25.25 Dumps Exam Questions: https://drive.google.com/open?id=1IfIfRUpLxIr9vCuBb0hsTdjbDfEW48xM
Full 3V0-25.25 Practice Test and 64 unique questions with explanations waiting just for you, get it now: https://www.dumpstorrent.com/3V0-25.25-exam-dumps-torrent.html